
The working assumption in most teams by now is that a capable model, shown the schema, writes the query a careful analyst would. It mostly does. Asked for Q1 2026 revenue per enterprise customer on a three-table PostgreSQL 18 schema, Opus 5.5 avoided a duplicate-row trap in the tags table without being told about it, chose the payment date over the cart date, and wrote the same query in five runs out of five. All five overstated revenue by 10%: $1,762,496 against $1,601,792. All five also said why, in a comment above the SQL: “The status codes are undocumented, so status is not used.” Status 3 meant refunded. The model had read everything the database said about itself, and the database never said that.
The same question against three versions of one schema
The fixture was built for this test, so its gaps are planted rather than found, and it is small: 2,000 customers, 60,000 orders, and a customer_tags table in which one customer in five carries the tag enterprise. It has three gaps that real schemas tend to have. orders.status is a smallint with three values and no documentation, where 1 is awaiting payment, 2 is paid and 3 is refunded. orders has two timestamps, created_at for when the cart was opened and paid_at for when the money arrived. And a legacy import tagged 24 of the 400 enterprise customers twice, which nothing prevented because customer_tags had no unique key.
The model got the question three ways, five times each. The first two runs put the output of pg_dump --schema-only in the system prompt and gave the model no tools. In one copy of the database that dump had names, types and primary keys only. In the other, the same data had a primary key on customer_tags (after removing the duplicates), foreign keys, a CHECK on status, and five column comments, one of them '1 = awaiting payment (paid_at is NULL), 2 = paid, 3 = refunded (paid_at is kept). Revenue counts status 2 only.' The third condition had the bare dump plus a shell tool that ran read-only queries as a role with default_transaction_read_only on, which is roughly what a database MCP server gives an agent. Every run used Opus 5.5 through Claude Code in print mode, and every answer was graded by running its SQL and comparing all 400 per-customer totals with the correct ones.
| Condition (5 runs each) | Correct | Total returned | Median time | Median cost | Turns |
|---|---|---|---|---|---|
| Catalog only: names, types, primary keys | 0 of 5 | $1,762,495.70 (+10.0%) | 10.8 s | $0.025 | 1 |
| Catalog + read-only access to the data | 5 of 5 | $1,601,791.94 | 49.3 s | $0.111 | 7–11 |
| Documented catalog: keys, CHECK, comments | 5 of 5 | $1,601,791.94 | 8.5 s | $0.017 | 1 |
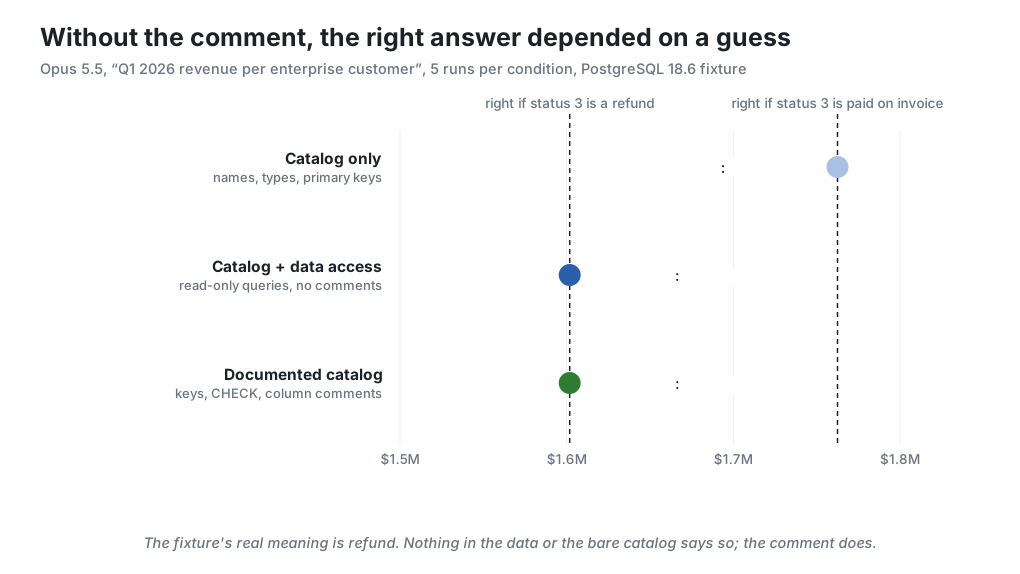
The catalog-only runs did better work than the 0 in that table suggests. All five guarded the tags join, four with EXISTS and one with DISTINCT, and every one gave the missing key as the reason: “customer_tags has no unique key, so a join could double-count.” So the model read the missing constraint as a warning. A plain join would have added $91,887 for the 24 doubled customers. All five used paid_at and stated that choice as an assumption too. The one decision they could not make was the one the schema gave them nothing to make it with, and they left status out and said so.
There is a detail in that wrong total worth sitting with. $1,762,495.70 is exactly the right answer if status 3 means “paid on invoice” instead of “refunded”. The data looks the same under both readings, since both have a paid_at and both are a minority of rows, so the bare-catalog model and the agent below were each right under one reading of the same column. Only the comment decided which reading was true.
Letting the agent read the data
The 2026 answer to a model that lacks context is to let it look. At Google Cloud Next in April, Google announced managed remote MCP servers for AlloyDB, Cloud SQL, Spanner, Bigtable and Firestore. Databricks wrote in March that agents on Lakebase create roughly four times as many databases as human users do. An agent with a connection can profile a column before it filters on it, which is the check an experienced analyst runs by habit.
And in the test it worked. The agent got all five runs right, and its reasoning was sound: status 1 never had a paid_at, so it looked unpaid; status 2 was about 80% of orders; status 3 had a payment date but was a small share, so it “looks like refunds”. It also found the doubled tags, noticed that the extra copies all carried the same timestamp (2025-03-14 02:00) and called that a bulk load. Every run said the meaning was inferred, and most said what to change if the guess was wrong, one of them in so many words: “If status 3 turns out not to mean refunded, change the filter to status IN (2, 3).”
That sentence is the limit. The data supported “refund” because refunds happen to be rare and keep their payment date, and an invoicing status would look identical. Had status 3 meant paid on invoice, the same reasoning would have produced the same query and come in 9.1% short. The agent was honest about the guess, which moves the problem to the person reading the answer: to judge the caveat, they need to already know what status 3 means, and someone who knows that did not need to ask.
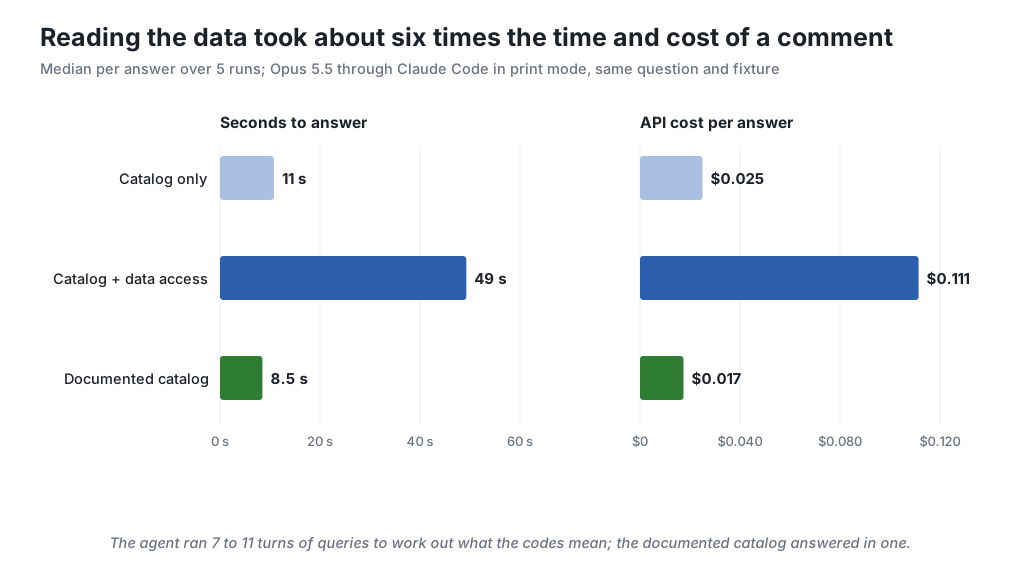
Inference also costs something on every question. The agent took 7 to 11 turns and a median of 49 seconds and $0.111 per answer, against 8.5 seconds and $0.017 for the documented catalog, which answered in one turn because it had nothing to work out. The comment is written once, and the inference is paid for again with every question anyone asks.
Better models are the other half of the obvious fix, and the benchmark numbers look like they deliver it. The Spider 2.0 paper, built on enterprise databases that often have over 1,000 columns, reported that an o1-preview agent solved 21.3% of its tasks. By November 2026 the Spider 2.0-Snow leaderboard tops out at 96.70. In January, though, Jin, Choi, Zhu and Kang checked the reference answers themselves and found errors in 62.8% of Spider 2.0-Snow tasks and 52.8% of BIRD Mini-Dev. Re-scoring 16 agents on a corrected BIRD subset moved them by -7% to +31% and reshuffled the ranking by up to nine places. A leaderboard measures agreement with an answer key, and no one has an answer key for your schema.
Where the meaning has to be written down
The test splits the gaps into two kinds. Some a model can discover, given time and a connection: duplicates exist or they don’t, a column is NULL in some rows or it isn’t. Others are facts about the business that the data is merely consistent with, and those are the ones only a declaration can carry. The table sorts the common gaps that way and points at the post that covers each one.
| Gap | What reading the data tells an agent | What only a declaration says | Covered in |
|---|---|---|---|
Relationships not declared (creator_id, placed_by) | Value ranges that overlap with some table’s ids | Which table the column refers to: a foreign key | Primary and foreign keys |
Bare id columns on every table | Nothing; a.id = b.id joins any pair and returns rows | The naming that makes the join obvious | Generic id primary keys |
| One column pointing at several tables | A type column next to an id column | That the join depends on the type, and how | Polymorphic references |
| JSON and TEXT payloads | The keys in whichever rows it samples | The other key names older rows still use | TEXT and JSON columns |
| References into another database | Nothing, from inside one connection | That the other side exists | Cross-database joins |
Coded values (status, type, flag1) | How often each value occurs, and which other columns are empty with it | What each value means: a comment or a CHECK | Comment your schema |
| Test rows and sentinel values | Outliers, if it looks for them | That [email protected] is not a customer | Schema is not data |
| Duplicates in a bridge table | That duplicates exist, if it counts | That they must not: a unique key | Uniqueness and selectivity |
| Business definitions (“active customer”) | Nothing | A view, a generated column or a CHECK | Where business logic lives |
| Collation and charset differences | Joins that return fewer rows than expected | One collation per database | Collation drift |
Naming that changed by era (userId, user_id) | Both spellings in use | Which one is current | Schema conventions |
The middle column is what the 2026 tooling added, and it is real. Before agents had connections, everything in that column was out of reach too. It is also slow, paid per question, and a guess wherever the right column says something the data only hints at. When a team’s code defines the model in an ORM, the right column often exists, but in a model class the database never sees, which is the argument of ORMs are a coupling.
Checking the result is the part none of this replaces. Application code has a compiler and a test suite that reject a broken change before anyone reads it. SQL has a parser, which accepts a wrong predicate as happily as a right one, and most teams review queries by reading them, which is exactly the check a fluent wrong query passes. Testing your database and its second part cover what an actual test of a query looks like. A richer catalog gives a test more to fail on.
What the industry built in 2026, and what it costs
Vendors reached the same conclusion and built a layer for it. Google’s QueryData announcement in April explains the accuracy gap with “Values can be ambiguous”, using a return-status column whose values are 1, 2 and 3, which is close to this fixture, and fixes it with a “schema ontology” of “descriptions of columns, tables and values”. Snowflake made Semantic View Autopilot generally available in February to generate semantic views from query history. Databricks’ release notes say Genie Code now “prefers governed metric views over ad-hoc SQL datasets”. And the Open Semantic Interchange spec, meant to let those layers move between tools, shipped a first version in January and has since become Apache Ossie (incubating). Atlan’s summary puts it plainly: “Most third-party tools do not import OSI directly today.”
A semantic layer can hold things a column comment can’t: a metric defined across six tables, synonyms, example questions and the query each one should produce. Its cost is that it is a second copy of the schema’s meaning, kept somewhere the schema’s migrations don’t touch, and read by whichever vendor’s agent it was built for. A comment goes the other way. It lives in pg_description or information_schema.COLUMNS, changes in the same migration as the column, and every tool that reads the catalog sees it, psql’s \d+ included. The only published number for the in-database version is Tiger Data’s internal test of its semantic catalog, which reported “up to 27%” better SQL generation and noted that results varied a lot by schema. For definitions that span tables the semantic layer is the better home. For what a single column means, the column itself is.
COMMIT; DROP SCHEMA public CASCADE; escaped the read-only transaction in the original reference PostgreSQL MCP server. In 2026 the same class of bug was assigned CVEs in ProxySQL’s read-only tool, in DBHub and in AWS’s PostgreSQL MCP server. An agent that reads data can also be told what to do by it: in General Analysis’s Supabase demonstration a support ticket instructed the agent to copy a token table into the ticket, and “No permissions were violated.” The boundary that holds is a database role that cannot write and can only see what the agent needs. Agents with more than that have already deleted a production RDS database and its snapshots (March 2026) and a Railway volume with its backups (April 2026). No column comment helps with any of that.Start with the model’s own list of assumptions
Every catalog-only answer in this test came with a comment block listing what the model had assumed, and the list was the same each time: the status codes are undocumented, Q1 means paid_at in UTC, tags might repeat. Each of those lines is a missing COMMENT ON or a missing constraint, written down by the reader who needed it. Asking a model the ten questions your team asks most often, against the catalog alone, gives you that list for your own schema in an afternoon. The fix is three statements in this case, and in most schemas it is about that size per column:
| |
With those in place, the agent’s 49 seconds of detective work became an 8.5-second answer in one turn.